ICLR 2026录用论文

Reconstruction
Alignment Improves Unified Multimodal Models

视觉理解如何
促进图像生成

一种 自监督后训练方法,面向统一多模态模型。RecA 利用模型自身的视觉理解特征重建图像,将理解能力迁移到文生图与图像编辑。

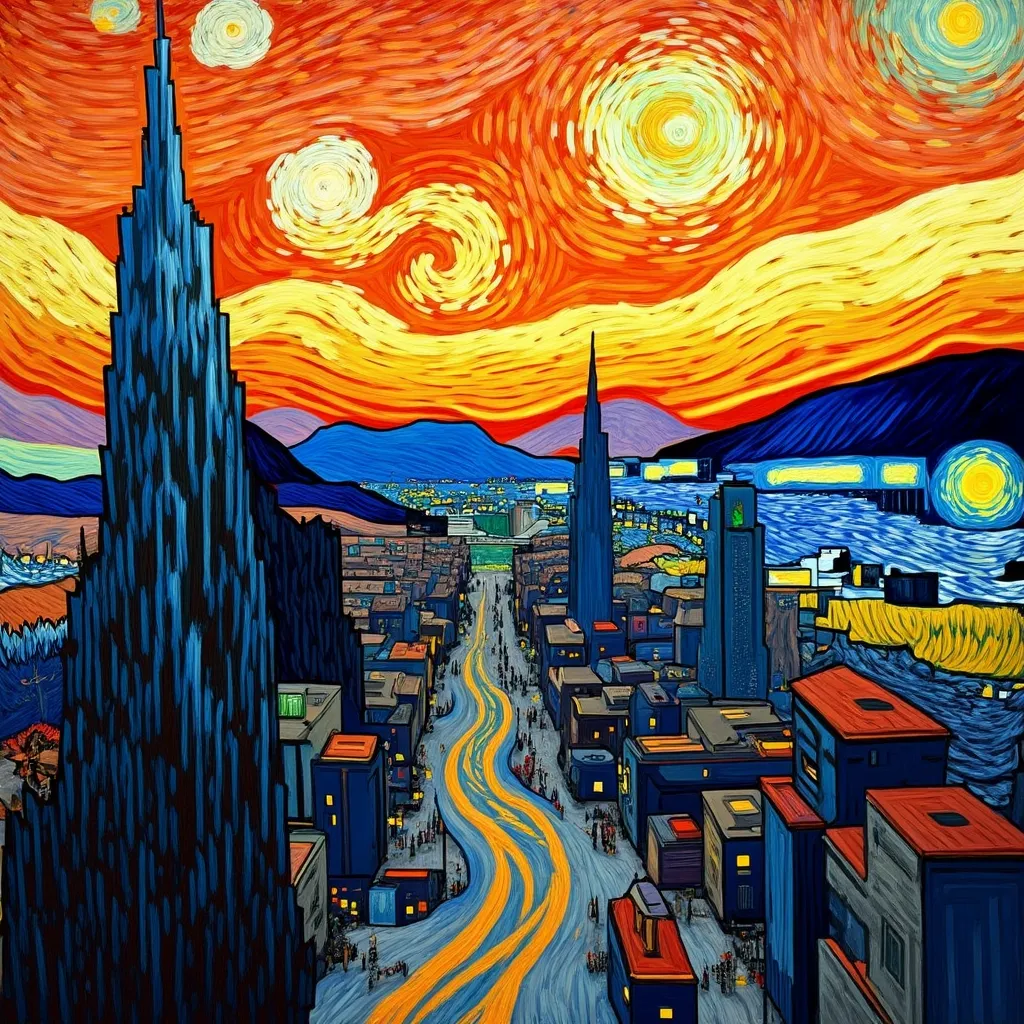
A Van Gogh style painting of a cyberpunk city at sunrise, generated with RecA.
梵高风格的赛博朋克城市日出。RecA 生成
1 UC Berkeley2 University of Washington3 Duke University

† 通讯作者

图像本身
就是监督信号

Reconstruction Alignment (RecA)让预训练的统一多模态模型根据自身的视觉理解特征重建图像,以原图作为训练目标。

这一 语义重建目标实现了理解到生成的能力迁移:提升文生图与图像编辑能力,并沿用模型原有的推理接口。
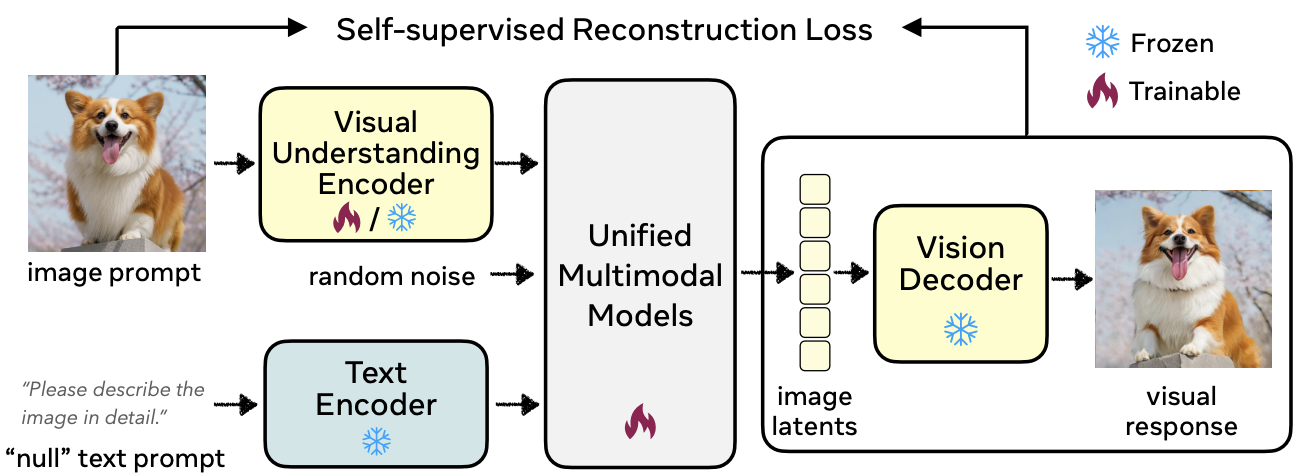
RecA training pipeline: an image is encoded into visual understanding features, which condition the model to reconstruct the original image.
面向统一理解与生成的自监督后训练。重建目标不需要为每张图像配备描述文本。
01

理解图像

以预训练模型的视觉理解特征作为条件信号。

02

重建语义

通过语义信息瓶颈,让模型在重建过程中学习有意义的视觉结构。

03

迁移到生成

文生图与图像编辑继续使用原有推理接口。

训练范围。重建目标无需图像描述。理解与生成共享参数的模型同时保留图像到文本训练,以维持理解能力;解耦的理解模块可以冻结。论文评测涵盖Show-o, Harmon, OpenUni, and BAGEL. 各模型架构的复现指南 ↗

监督信号的差距

图像包含的信息比描述更丰富

文字描述往往遗漏细粒度属性、空间关系与视觉细节。视觉理解特征能提供更密集的监督信号。
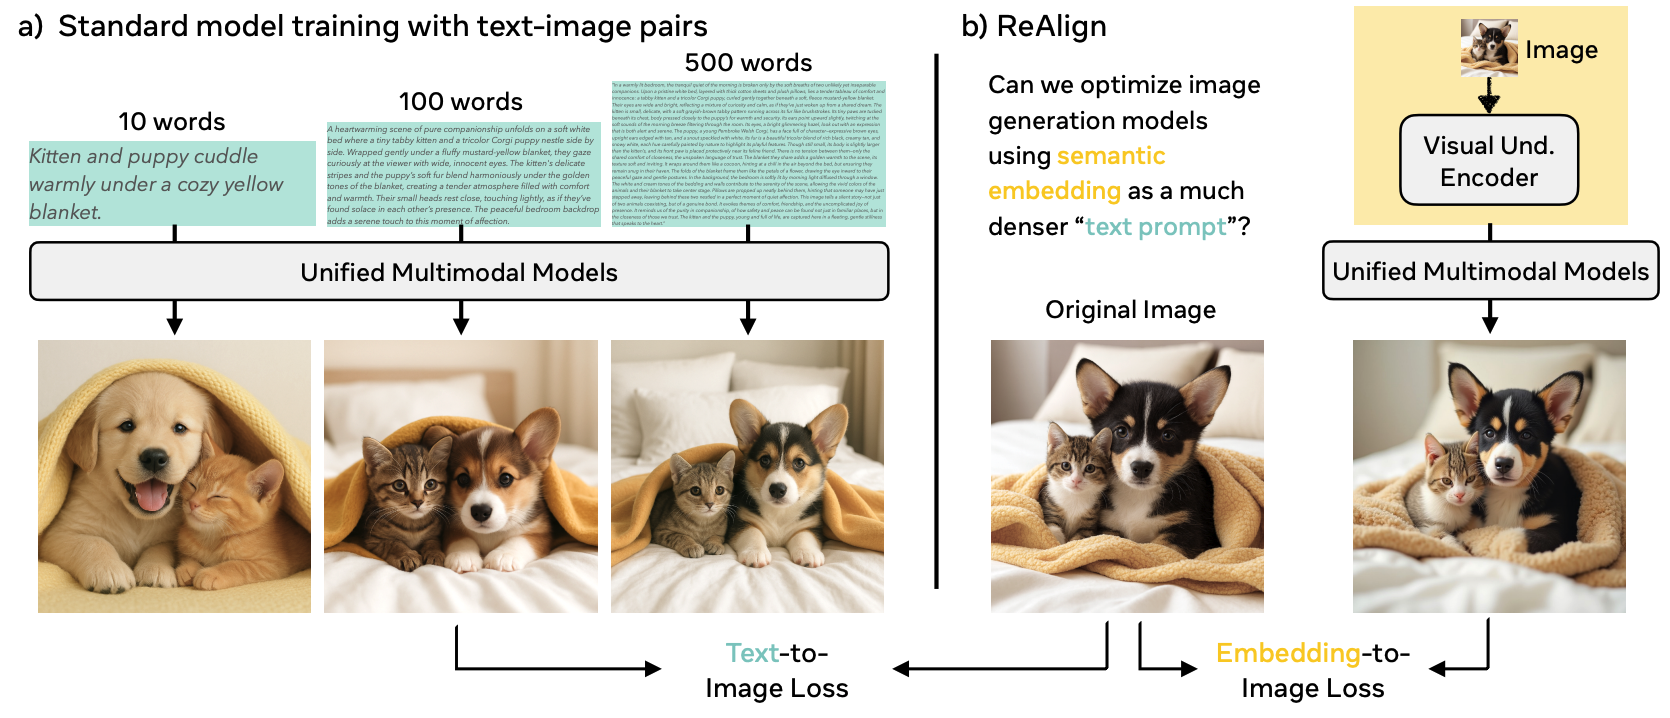
Comparison of sparse text-caption supervision with dense visual understanding features.
视觉特征保留了文字描述可能遗漏的信息。

理解与生成的差距

理解一个概念,未必能生成它

统一模型可能识别出一个视觉概念,却难以生成它。RecA 用语义重建连接这两种能力。
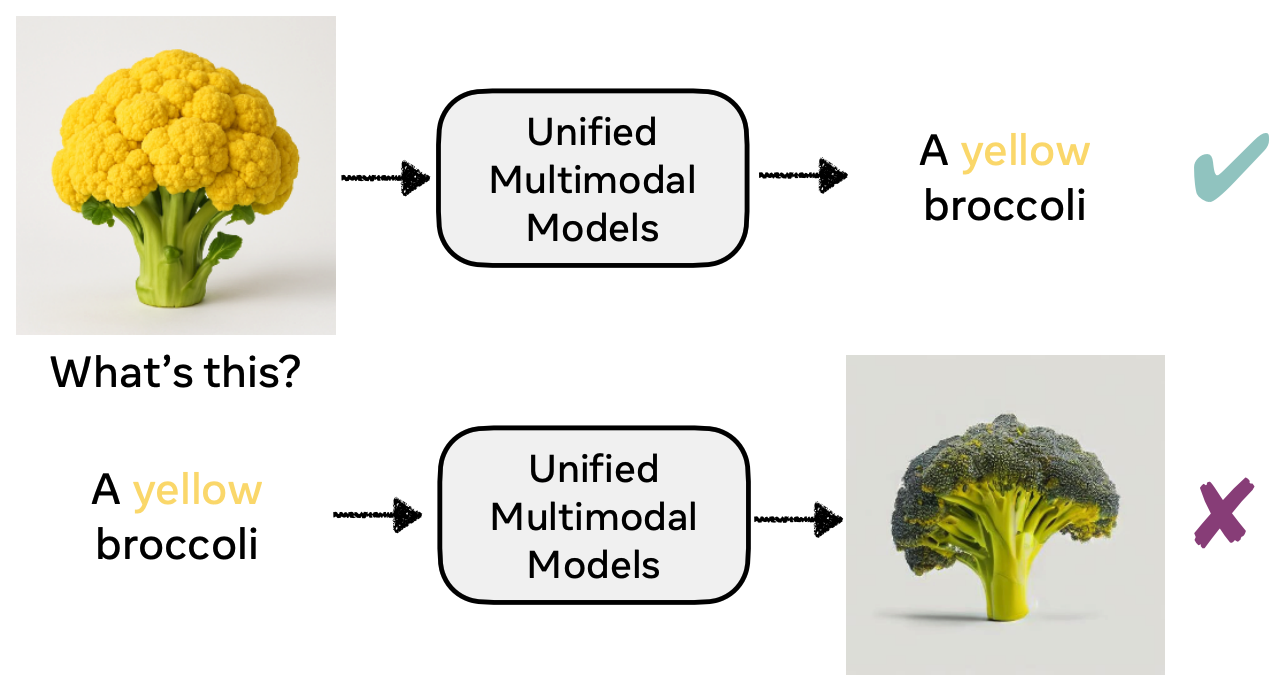
Yellow broccoli example illustrating a gap between a model’s visual understanding and image generation.
论文中的黄色西兰花示例展示了这种不一致。

03 / 实验结果

更好的生成
更强的编辑

利用视觉理解进行生成模型后训练,在不同任务与架构上取得提升。

文生图

Harmon-1.5B → Harmon-1.5B + RecA

GenEval ↑0.73→0.86
DPG-Bench ↑80.93→87.21

另一套独立的SFT → RecA配置先使用 GPT-4o-Image 蒸馏数据进行监督微调,再进行 RecA,达到0.90 GenEval / 88.15 DPG-Bench.

图像编辑

BAGEL → BAGEL + RecA

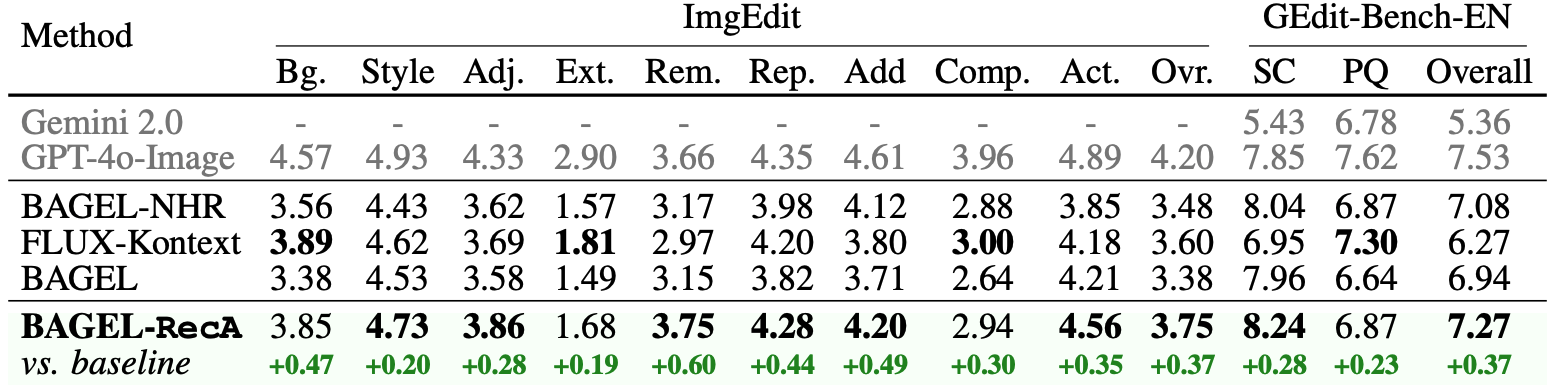
ImgEdit ↑3.38→3.75
GEdit-Bench-EN ↑6.94→7.27

这一 BAGEL 实验使用10,000 张无标注图像、1,000 个训练步,总计27 A100 GPU-hours.

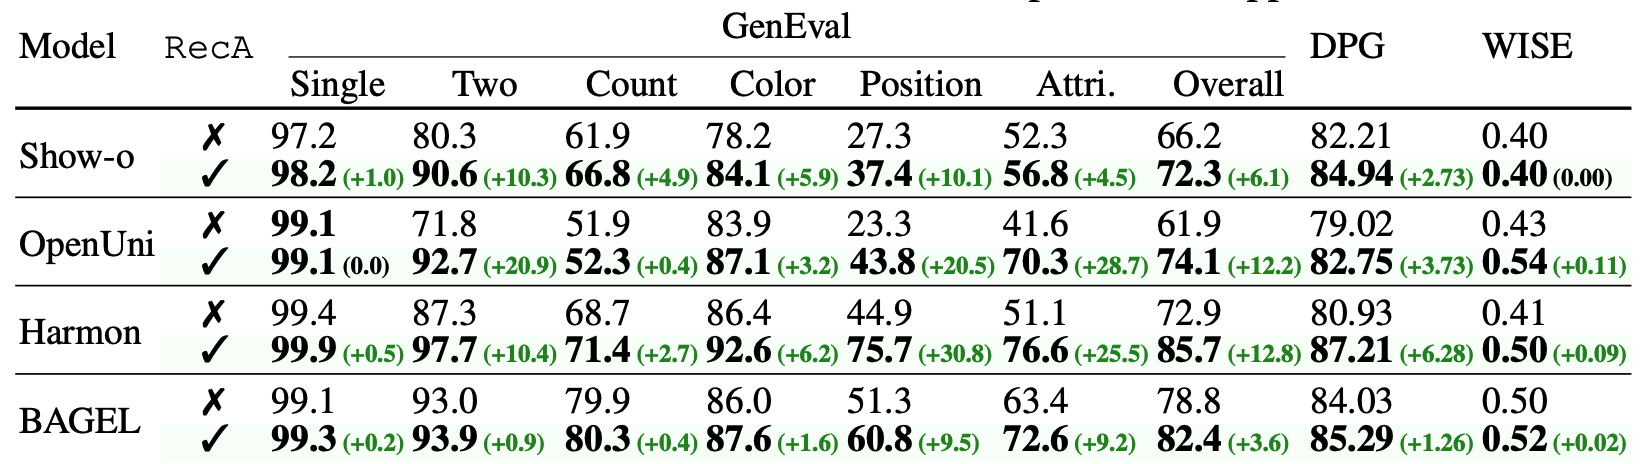
完整基准表格与分类结果
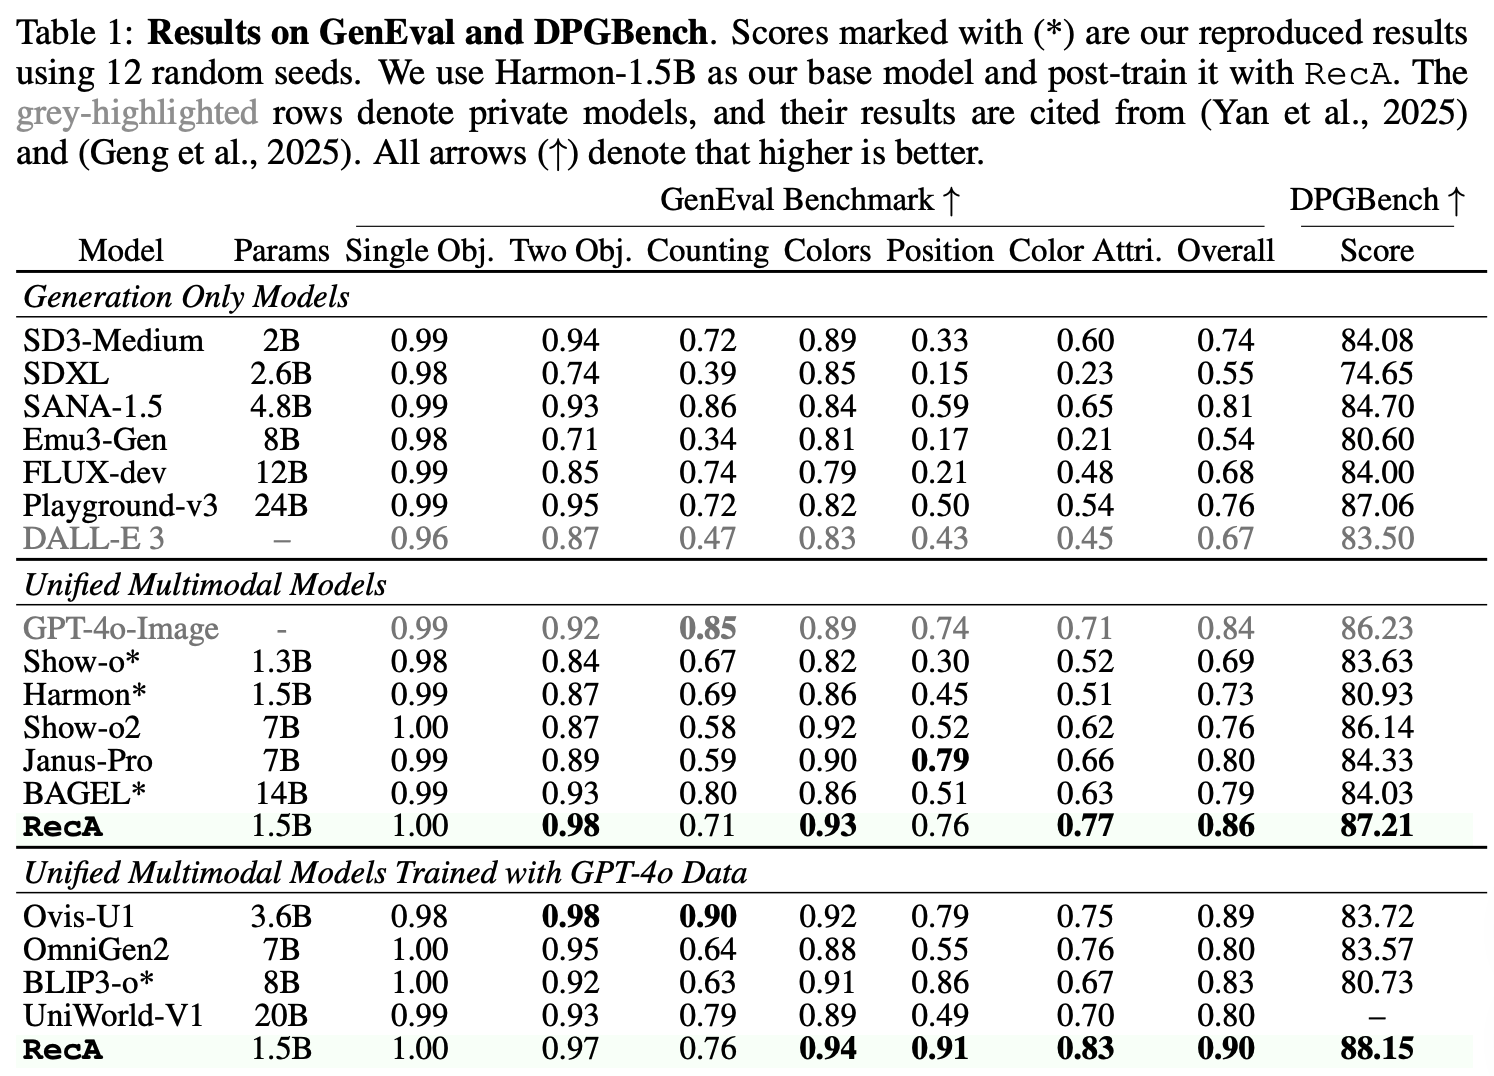
Full text-to-image benchmark comparison from the paper, including separate training recipes.
生成基准对比。
Per-category generation scores across Show-o, Harmon, OpenUni, and BAGEL.
不同架构与评测类别的生成结果。
BAGEL image-editing results reported in the paper.
图像编辑评测。
评测协议与完整实验↗

04 / 图像编辑

改变光线,调整细节

BAGEL-RecA 编辑示例。拖动分隔线,对比原图与编辑结果。
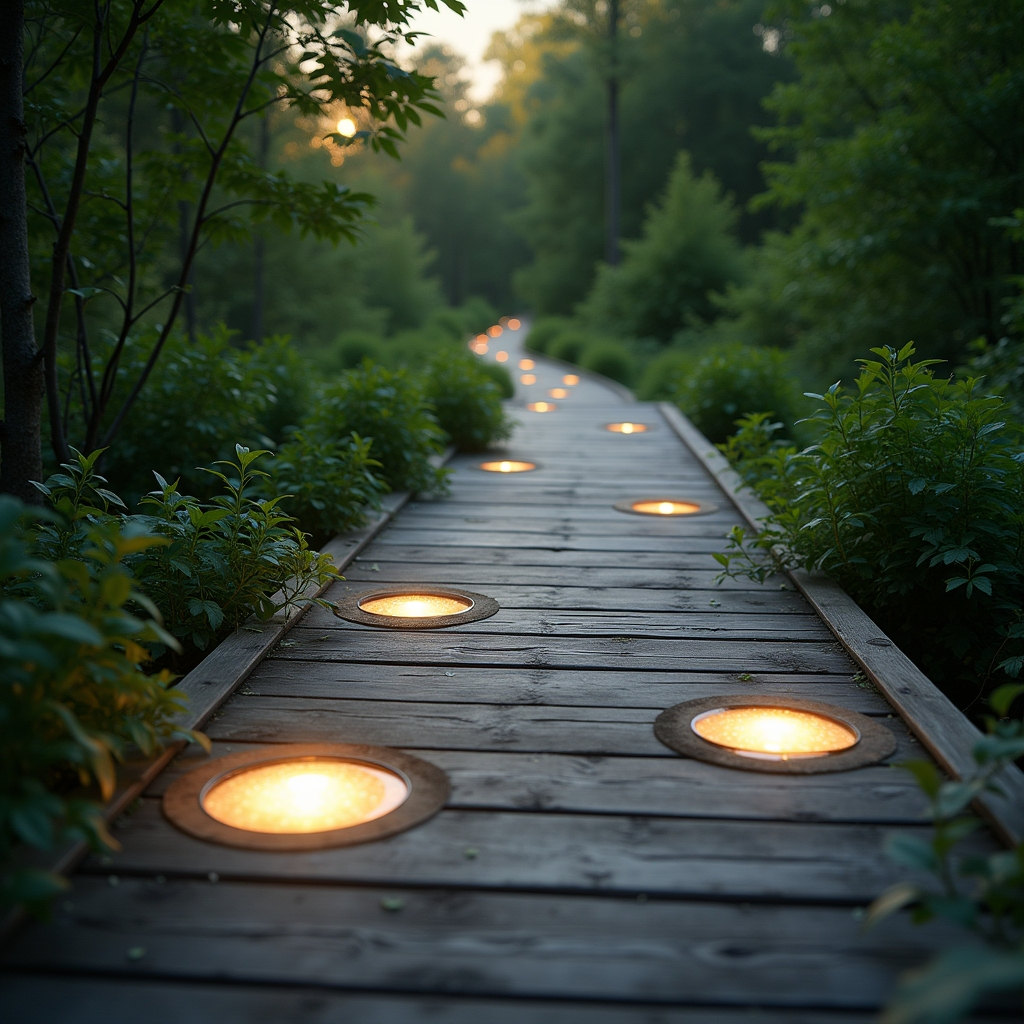
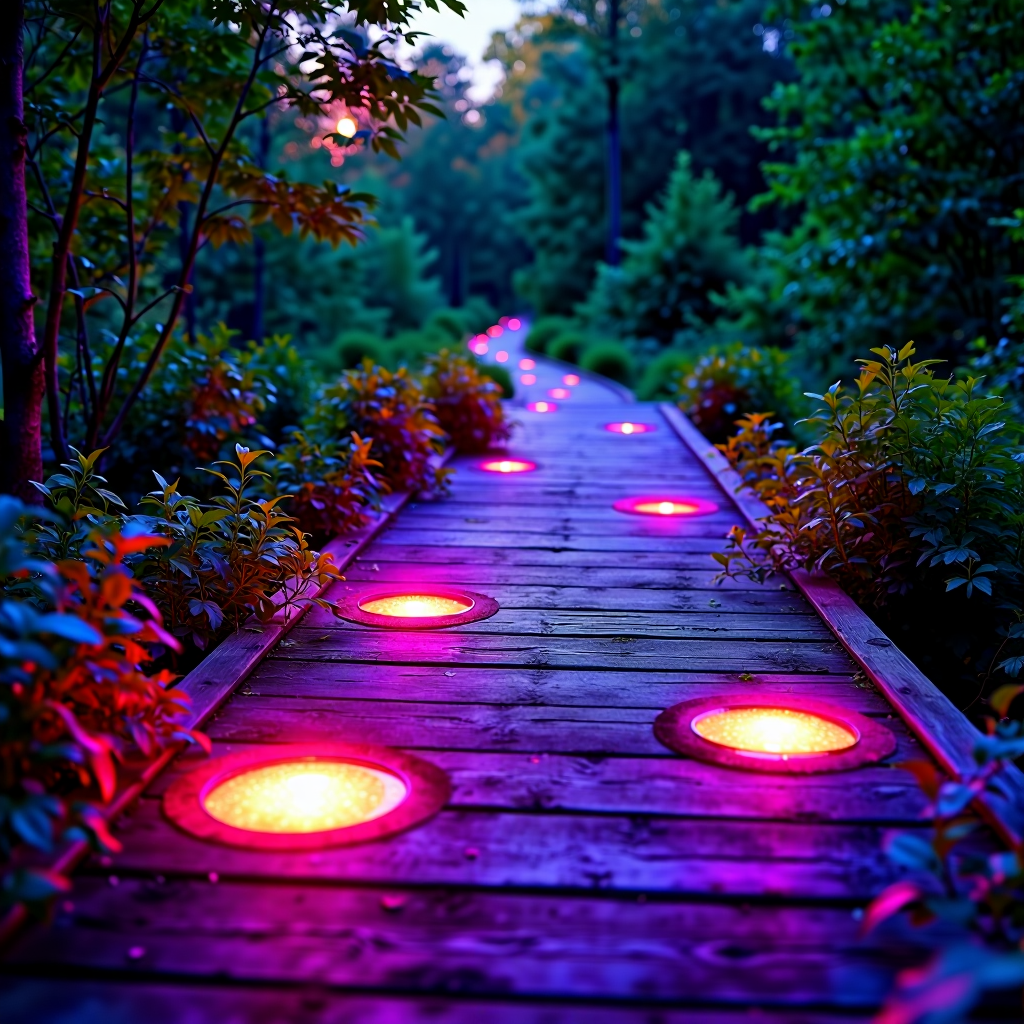
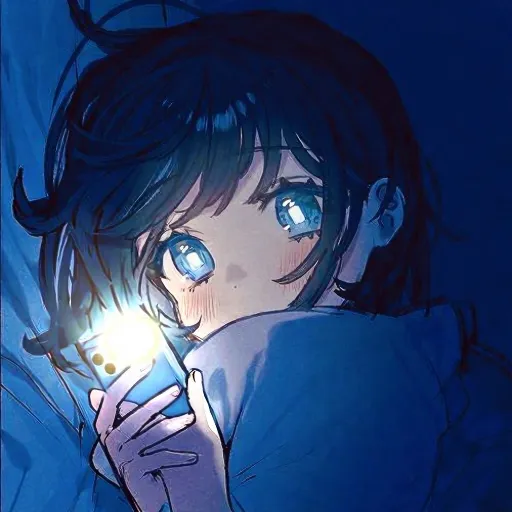
Original image before: Shed neon light on the scene.
Edited result: Shed neon light on the scene.
原图RecA
01Shed neon light on the scene.
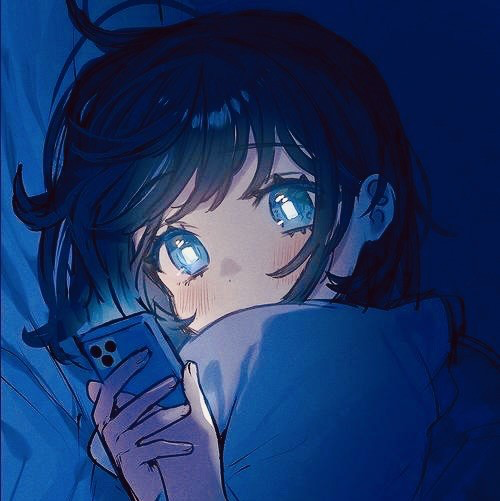
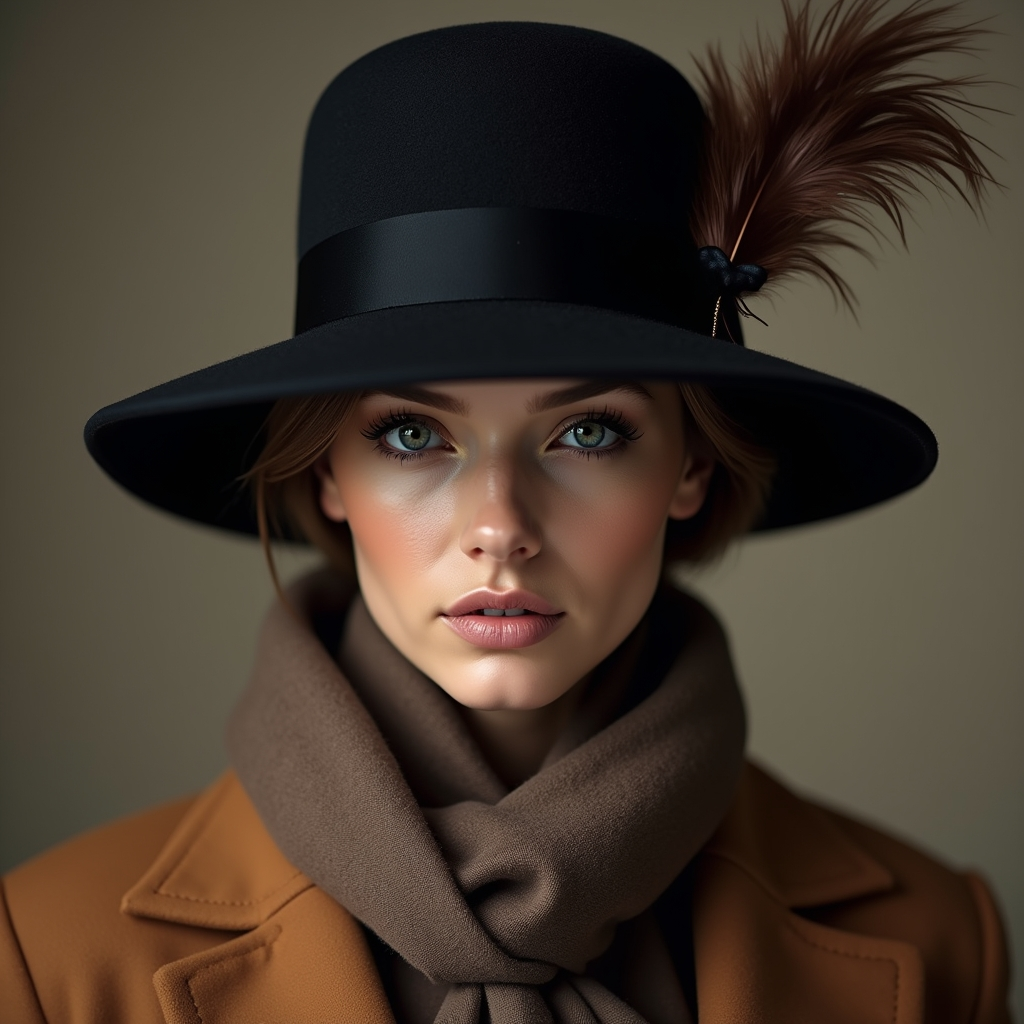
Original image before: Turn on the flashlight on the smartphone.
Edited result: Turn on the flashlight on the smartphone.
原图RecA
02Turn on the flashlight on the smartphone.
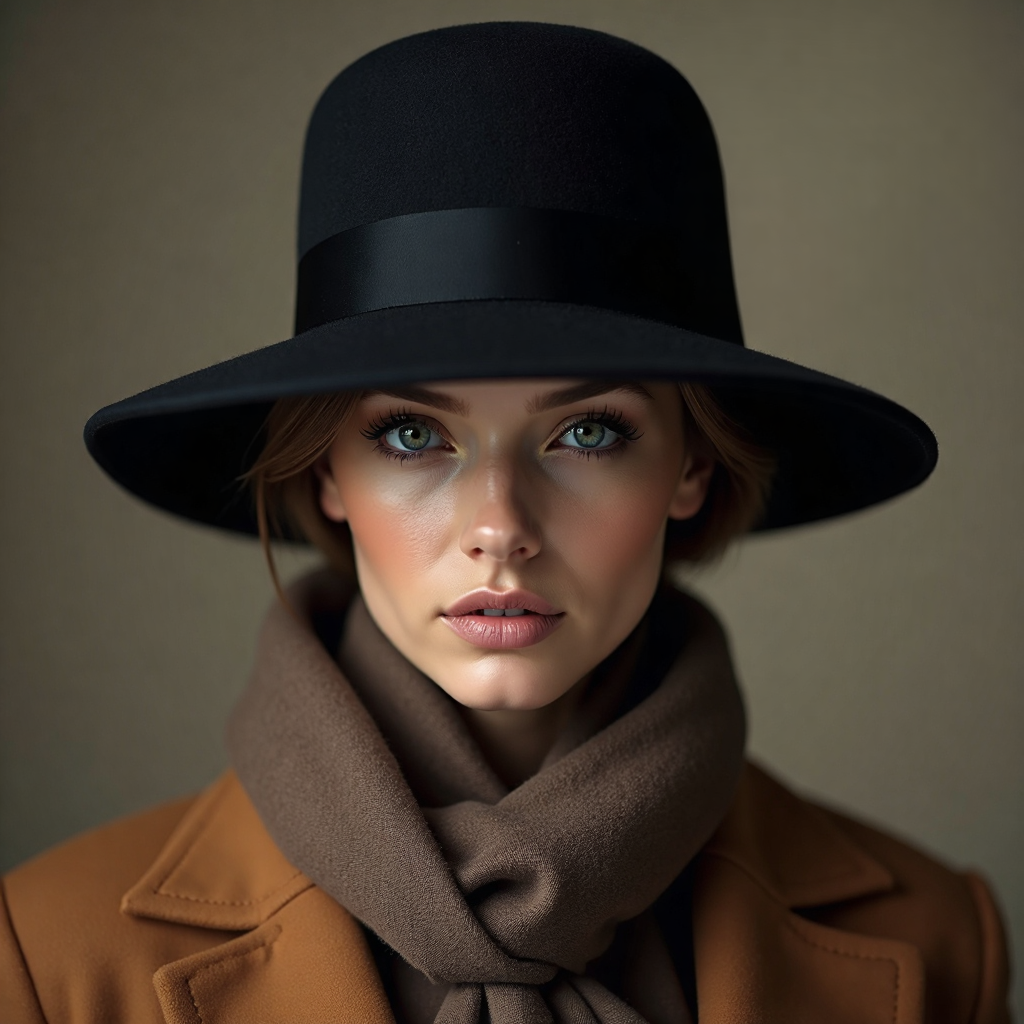
Original image before: Remove the feather on the hat.
Edited result: Remove the feather on the hat.
原图RecA
03Remove the feather on the hat.
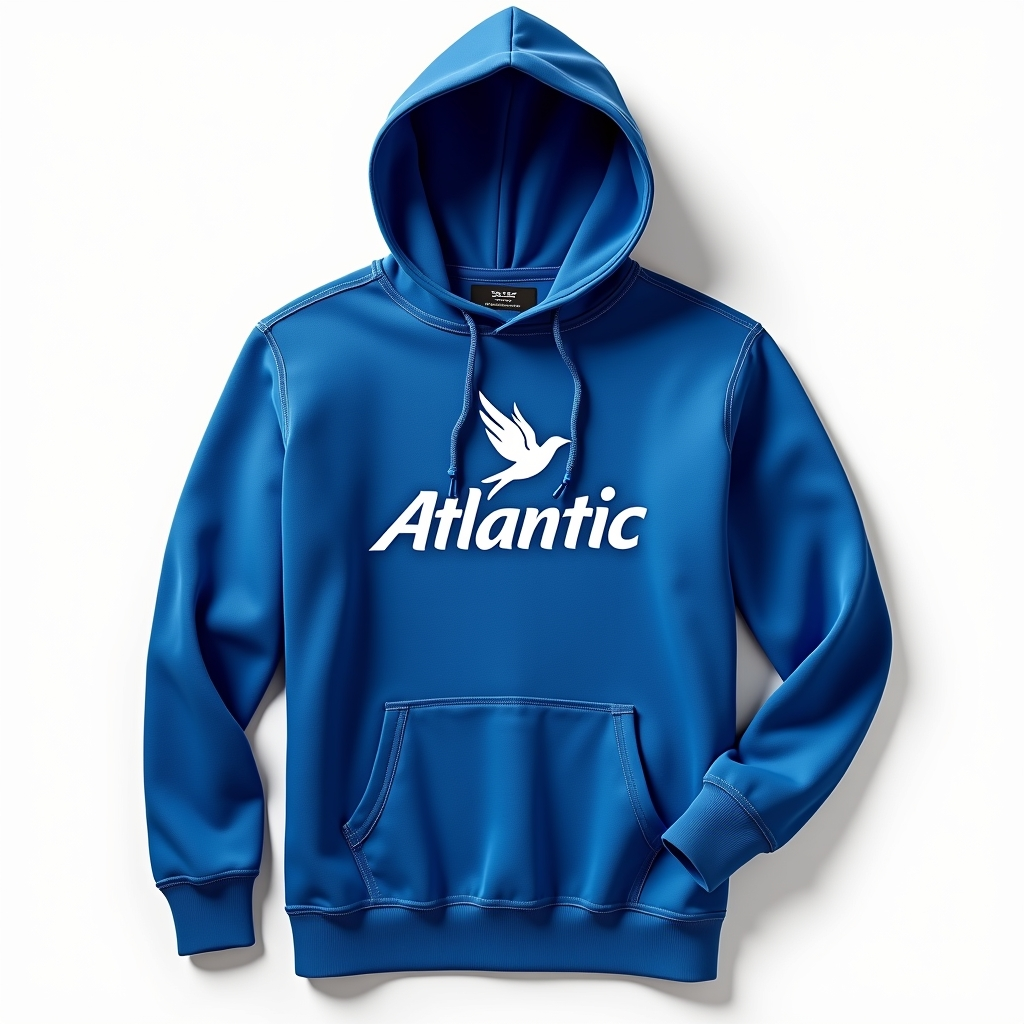
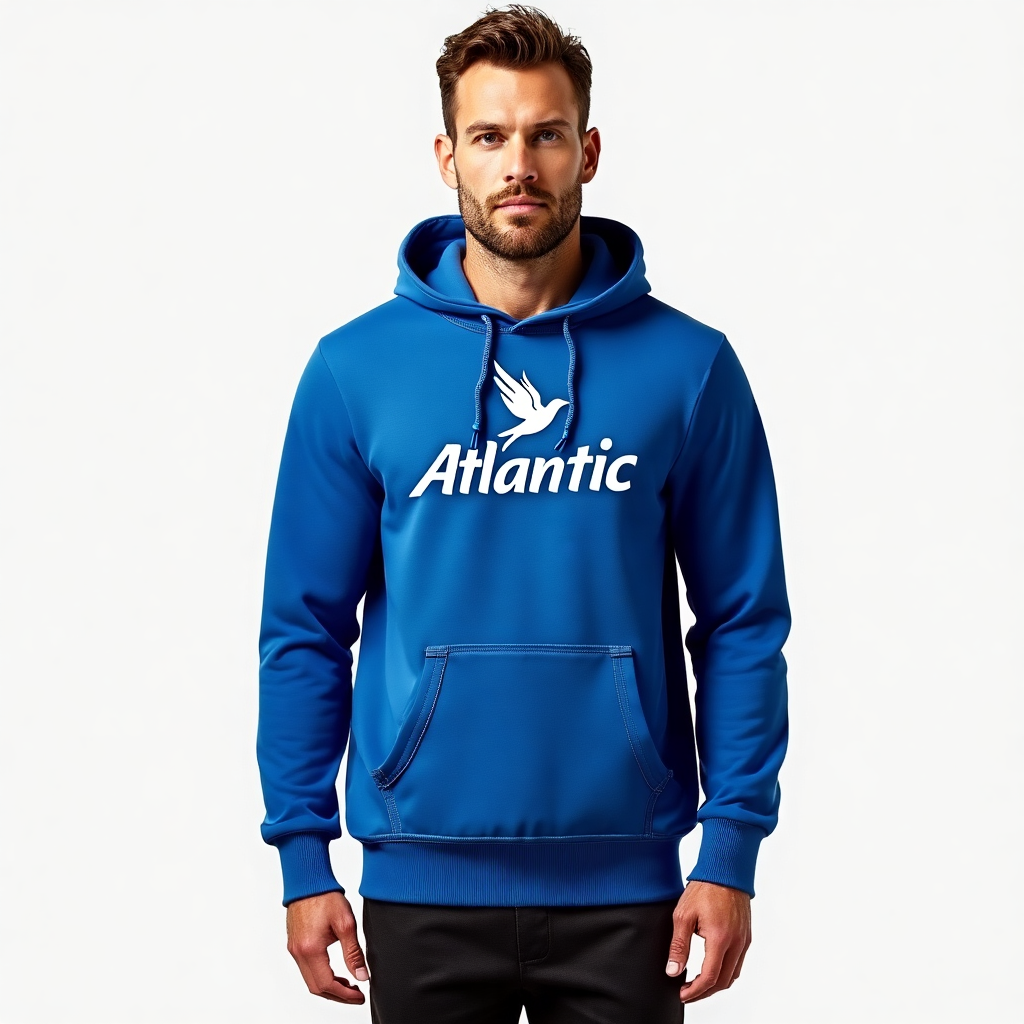
Original image before: A man is wearing the clothes from the reference image.
Edited result: A man is wearing the clothes from the reference image.
原图RecA
04A man is wearing the clothes from the reference image.
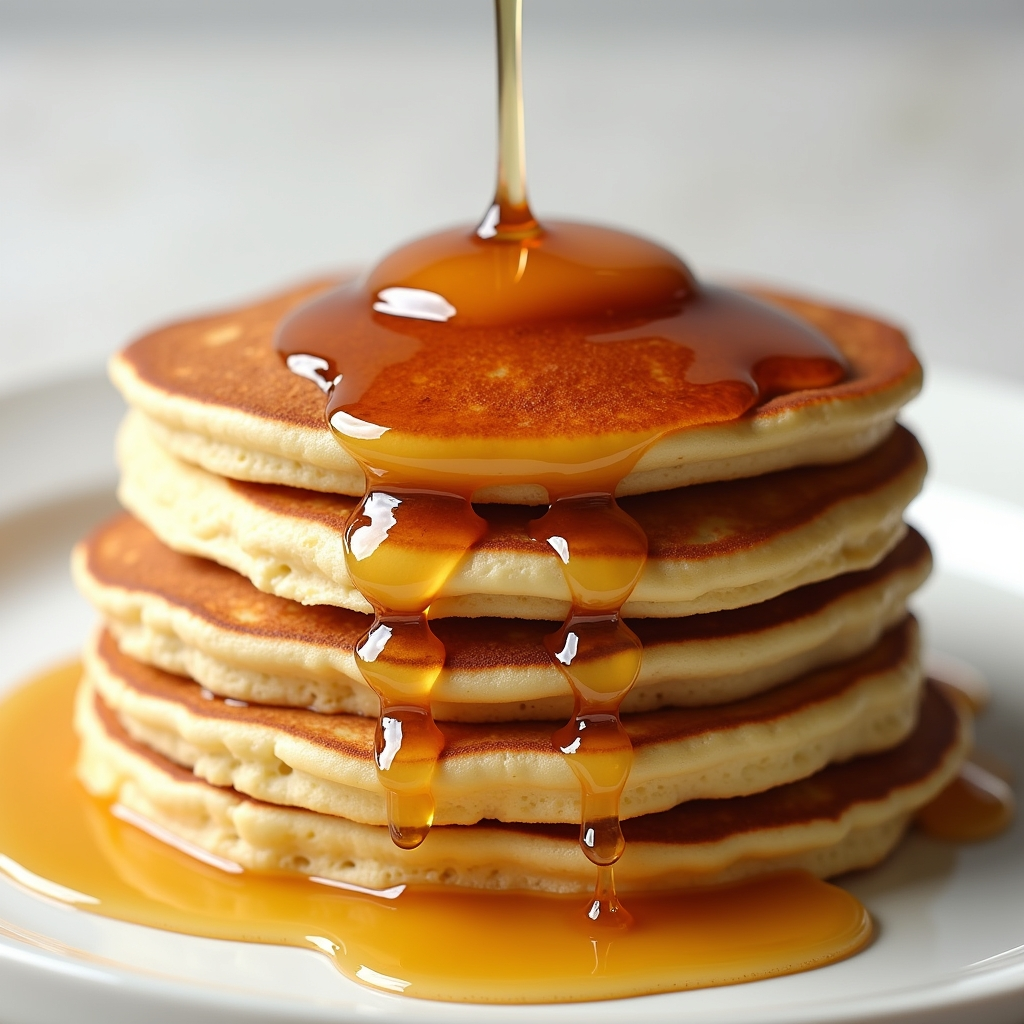
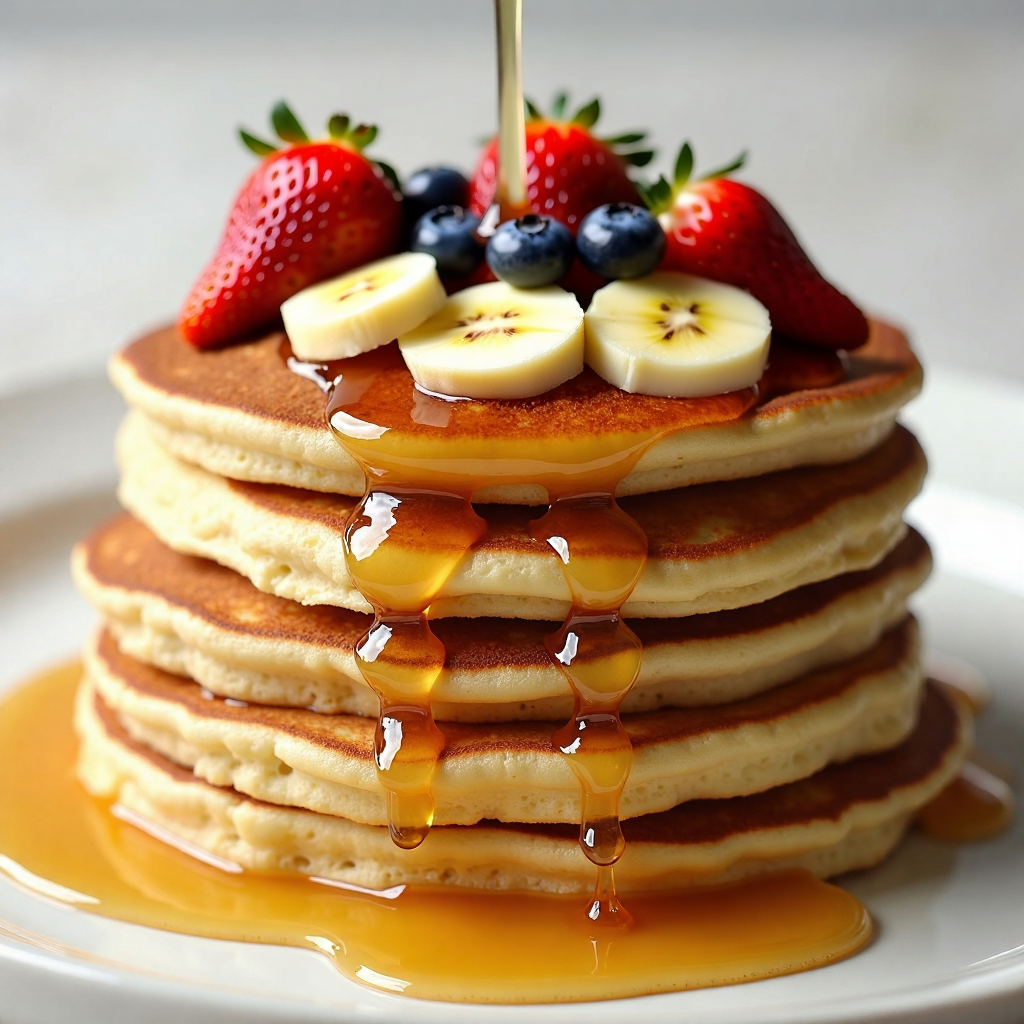
Original image before: Add strawberries, blueberries, and banana slices on top of the pancake stack.
Edited result: Add strawberries, blueberries, and banana slices on top of the pancake stack.
原图RecA
05Add strawberries, blueberries, and banana slices on top of the pancake stack.
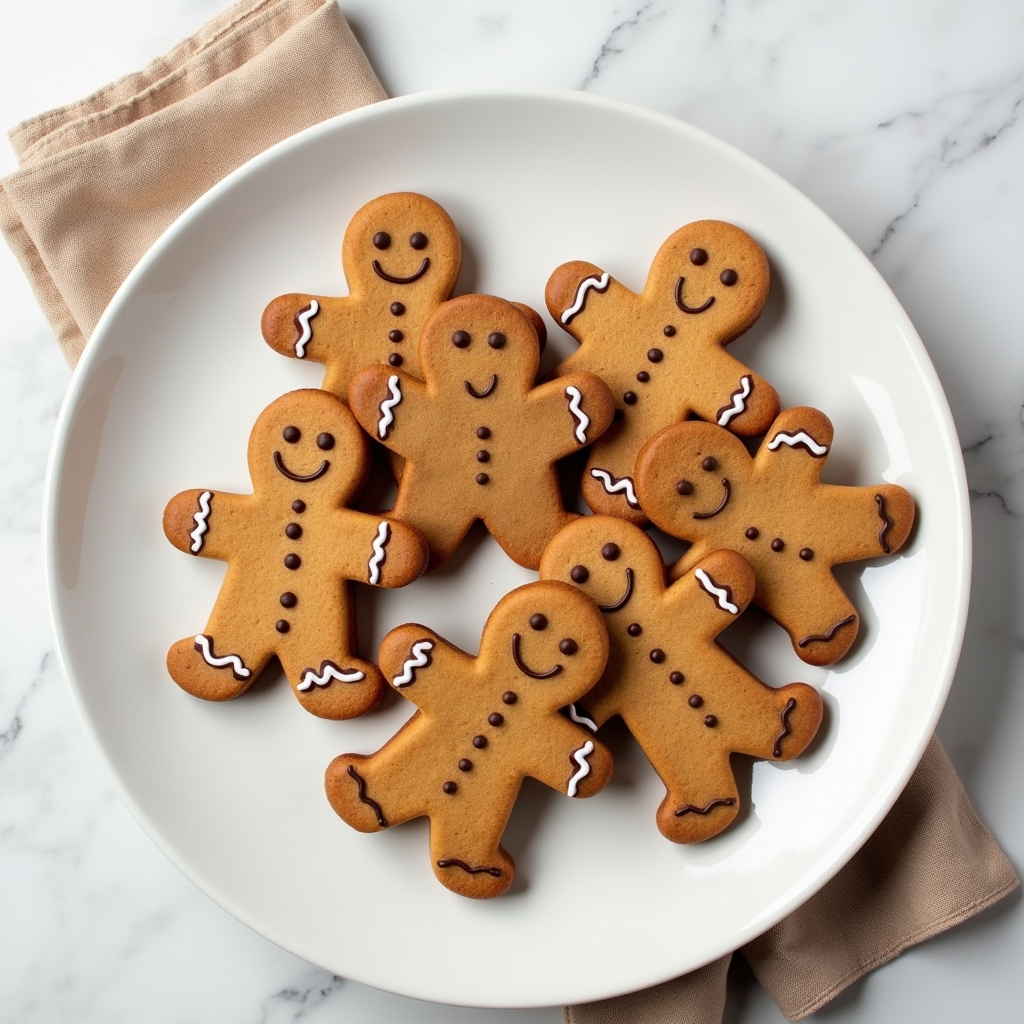
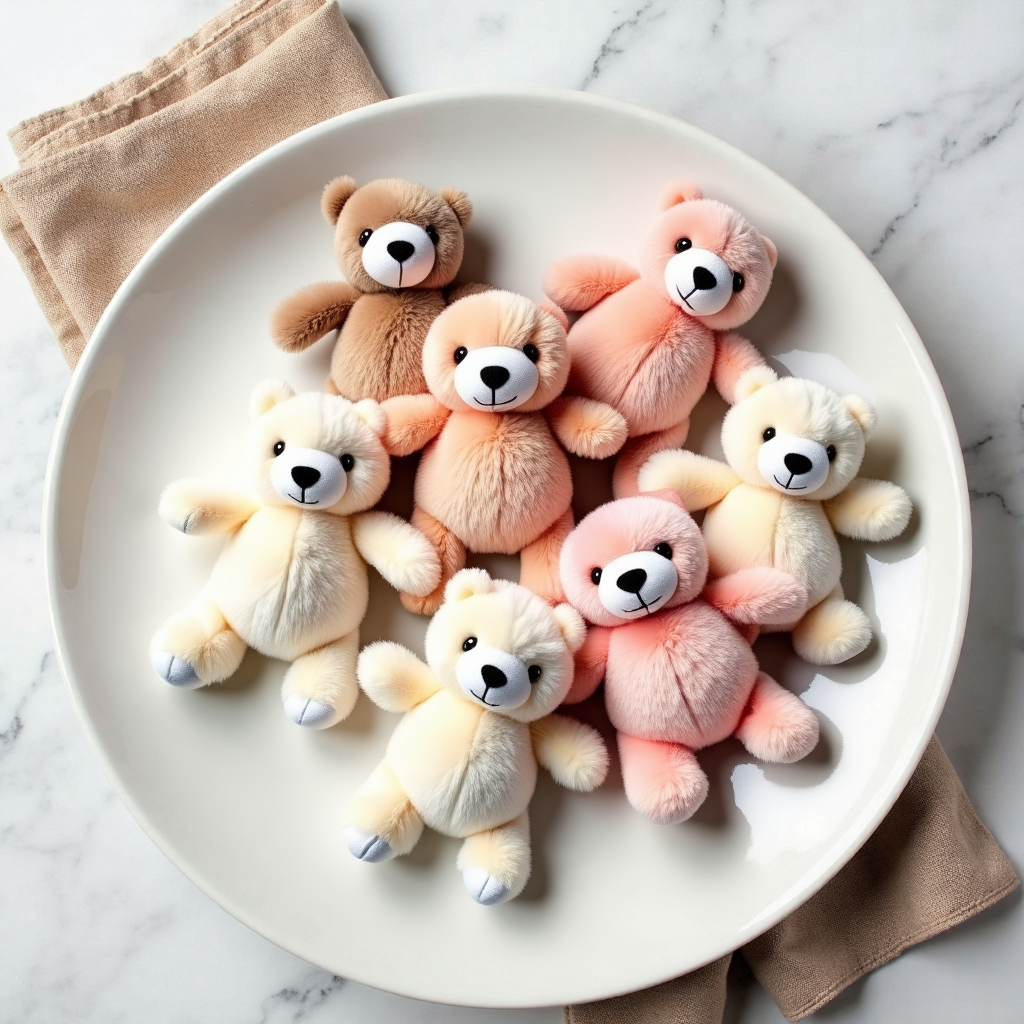
Original image before: Change the gingerbread cookies into soft plush toy figures, with fuzzy fabric texture.
Edited result: Change the gingerbread cookies into soft plush toy figures, with fuzzy fabric texture.
原图RecA
06Change the gingerbread cookies into soft plush toy figures, with fuzzy fabric texture.

键盘操作:聚焦对比图后,使用方向键调整。体验 BAGEL-RecA ↗

在这项工作上继续探索

如果 RecA 对你的研究有帮助或启发,欢迎引用我们的 ICLR 2026 论文。摘要与出版信息(英文)↗

BibTeX ↓
@inproceedings{xie2026reconstruction,
  title={Reconstruction alignment improves unified multimodal models},
  author={Xie, Ji and Zettlemoyer, Luke and Wang, Xudong and others},
  booktitle={International Conference on Learning Representations},
  volume={2026},
  pages={120095--120137},
  year={2026}
}